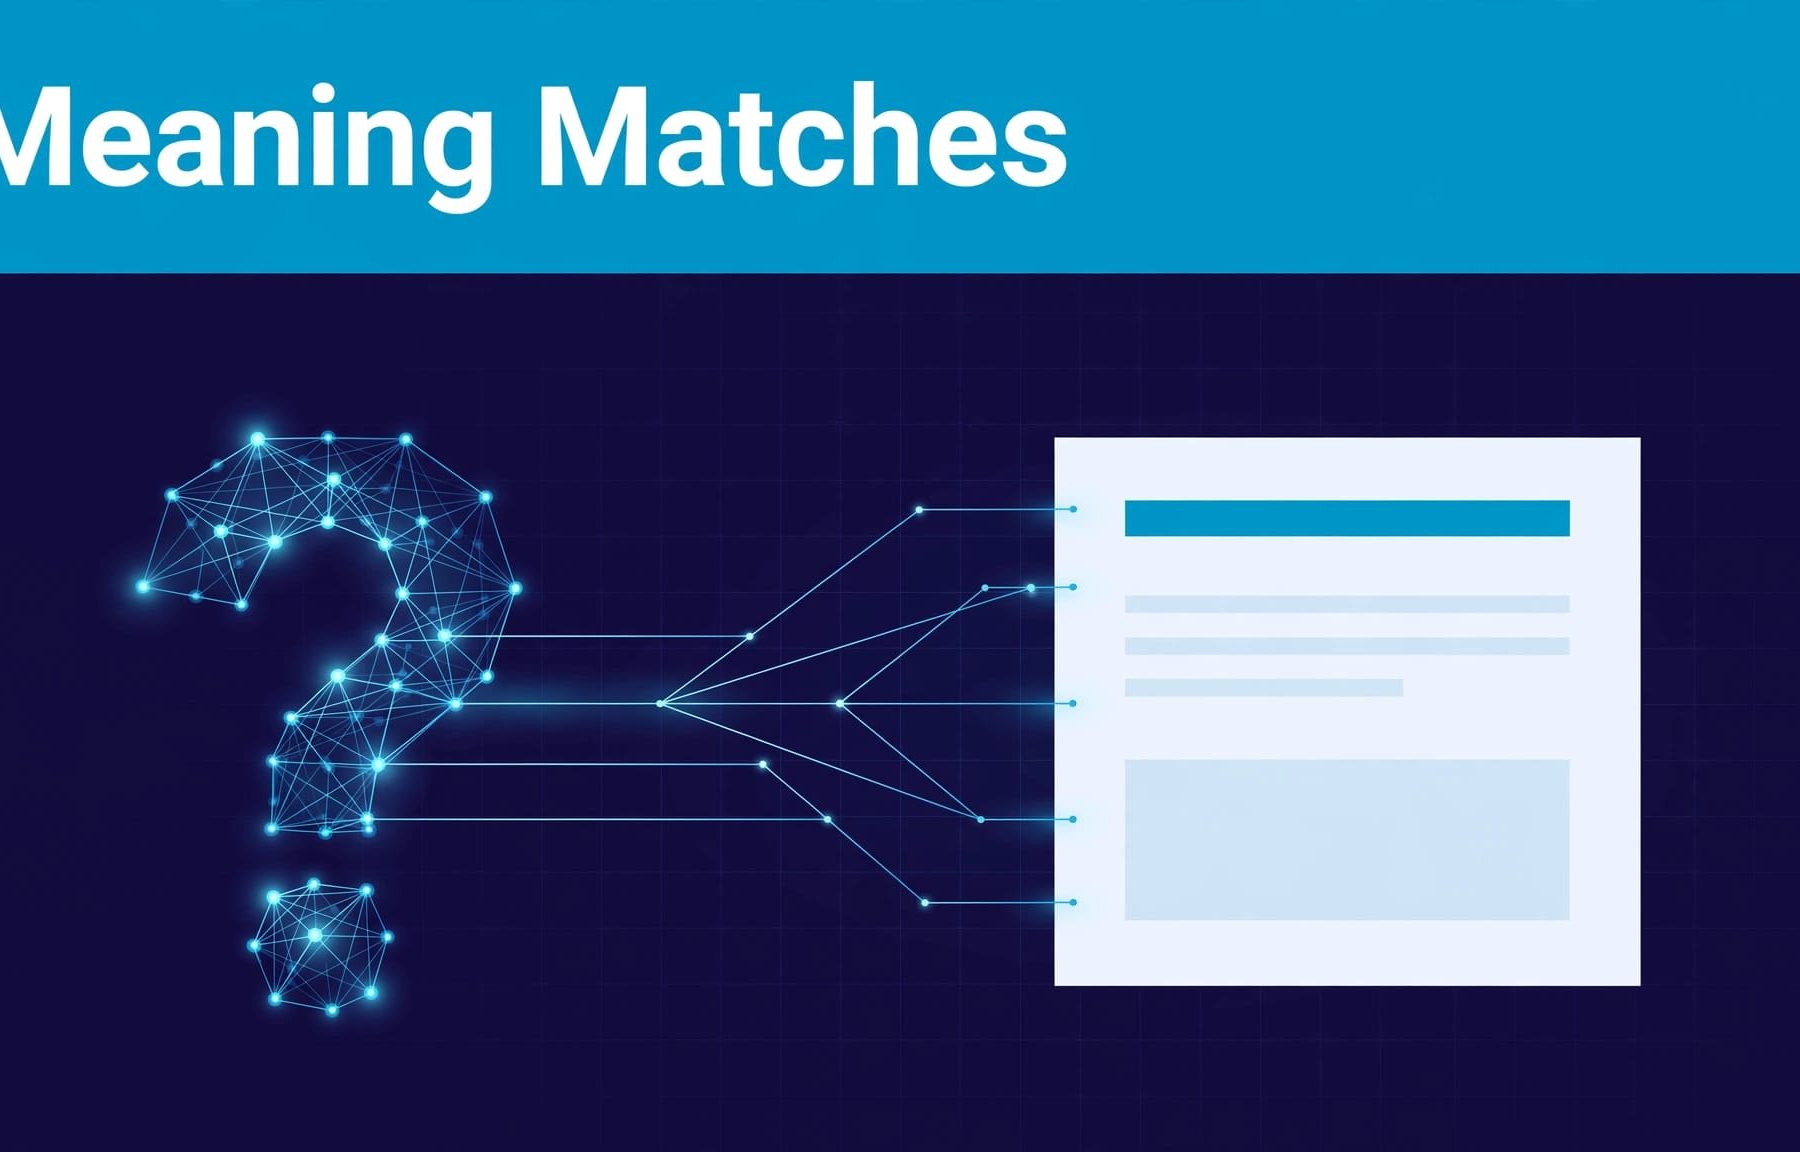
LLM embeddings can connect a buyer’s question about poor paid leads with a page titled ‘Google Ads audit’. They turn both pieces of text into text embeddings, which vector search compares for semantic similarity despite the different wording. The match is only a starting point: a useful answer still needs current information, accurate details and a reliable source the buyer can check.
For your team, this is a practical content question. Are your pages clear enough for a system to find the right passage, and strong enough for someone to trust it once they do?
How LLM embeddings connect questions with content
LLM embeddings help software compare the meaning of a buyer’s question with your content. Embedding models convert text into numbers called vector embeddings, creating text embeddings in a high-dimensional vector space, often known as a latent space. Related meanings tend to sit closer together, which indicates semantic similarity.
Earlier word embeddings represented individual words, while similar techniques now support recommendation systems. This section focuses on text retrieval; multimodal embeddings can also connect text with images or other media.
Match the question, not just the phrase
Suppose someone asks, ‘Why do our paid campaigns generate enquiries that sales rejects?’ Your page might discuss lead quality, conversion tracking and campaign targeting without using that exact sentence. Semantic search uses vector search to find relevant passages by meaning, based on semantic similarity.
This is useful when you group keywords around shared intent. ‘Poor-quality leads’ and ‘wasted ad spend’ may describe the same problem, while ‘how much does an agency charge?’ calls for different content. Similar wording doesn’t always mean the buyer needs the same answer.
Keep the commercial context
An embedding can suggest that two passages are related. It doesn’t know whether your page addresses a UK buyer, a particular platform or a company ready to purchase. Those details must remain visible in the question, the content and any filters used during retrieval.
Start with the language your prospects use in calls, search queries and sales emails. Then map keywords to buyer intent before deciding which page should answer each question.
What similarity scores can and cannot tell you
A retrieval system turns a buyer’s question and content passages into text embeddings, then uses vector search to rank candidate passages in vector databases. The scores reflect semantic similarity in a shared latent space, helping a search interface or answer-generating model find likely matches.
How cosine similarity works
Cosine similarity compares the direction of two vectors rather than relying on shared words. In vector search, vectors pointing in a similar direction receive a higher score, reflecting semantic similarity in the model’s latent space. OpenAI’s embeddings guide describes using this method to rank documents against a query.
You don’t need to calculate the score yourself to make content decisions. For example, ‘annual subscription costs’ might match ‘enterprise pricing’, even if a keyword-only search misses it. Other systems may use different similarity measures.
Why a close match can still be wrong
A passage about pricing may rank highly for a buyer’s question yet omit the minimum contract term. A case study might match the industry but describe a service you no longer offer.
Treat the score as a way to find candidates, not a judgement on accuracy. Dates, product names, locations and eligibility rules need separate checks. A highly ranked passage is of little use if it gives the buyer the wrong impression.
Prepare content buyers can find and trust
Before you think about vector databases, review the material you plan to index. A retrieval system reflects the sources you provide, including outdated pages, incomplete tables and unsupported claims. Text preprocessing and tokenization prepare material for text embeddings, which support vector search by comparing semantic similarity between a buyer’s question and a passage.
Start with owned, current sources
Build an inventory of product pages, service pages, documentation, approved case studies and frequently asked questions. Record who owns each source, when it was reviewed, which market it covers and whether it’s public or restricted. For relevant diagrams or scanned documents, multimodal embeddings can help index visual content; ordinary text pages don’t need them.
Your AI content briefs for better B2B leads can turn recurring sales questions into clear page requirements. Ask for a direct answer, its qualifications and evidence a buyer can inspect. If an old offer remains online, mark it as archived before it reaches the index.
Keep each passage useful on its own
Long documents are usually split into smaller passages, or chunks. Choose chunking strategies that leave enough context within the model’s context window. If a chunk contains only ‘Prices start at £500’, but the next contains the eligibility conditions, retrieval may return an incomplete answer. Keep the figure and its qualifications together.
The same care applies to PDFs and tables, where extraction can detach a number from its heading. Test different chunking strategies and passage sizes using real questions rather than assuming one setting suits every page. A content gap analysis based on buyer needs can also show where no suitable passage exists yet.
Build a retrieval workflow around buyer questions
Embeddings usually sit inside a wider retrieval process. Documents are cleaned, split using suitable chunking strategies, tagged with metadata and indexed in vector databases. When a question arrives, vector search finds likely evidence.

Retrieve passages before generating an answer
Use the same embedding model to create text embeddings for stored passages and incoming questions, so their vectors can be compared. Vector databases use vector search to find passages with high semantic similarity. At scale, approximate nearest neighbor methods, including an HNSW index, narrow candidates efficiently, though speed and accuracy depend on the setup.
Dimensionality reduction can shrink the index, but test its effect on retrieval quality.
LangChain’s semantic-search guide shows how to embed documents and queries, then retrieve text with vector search and semantic similarity. Retrieval-Augmented Generation (RAG) adds a step: an LLM uses selected passages as context to draft an answer.
Check the evidence before using it
For a straightforward, stable FAQ library, basic retrieval may be enough. Complex B2B questions often need metadata filters, keyword search and a cross-encoder to rerank candidate passages against the full question.
If a buyer asks about a Salesforce integration and UK data storage, a passage covering only the integration is incomplete. The system may need evidence from two approved sources. Keep their page references attached, and require the answer to say when the available material doesn’t support a claim. More text in the context window won’t fix missing evidence.
Use hybrid search for exact commercial details
Text embeddings help match varied buyer language through semantic similarity. Exact matching still matters for product codes, regulations, campaign names and dates. Hybrid retrieval combines vector search with keyword methods such as BM25 in vector databases, then reranks the candidates.
The right method depends on what the buyer asks:
| Buyer question | What retrieval must preserve | Useful content response |
|---|---|---|
| ‘Why are our paid leads poor?’ | Related ideas about targeting and lead quality | Explain diagnostic steps and what the data can show. |
| ‘Do you support Salesforce?’ | The exact product name | State the supported integration and any limits. |
| ‘What’s included in a Google Ads audit?’ | The service name and current scope | Give a clear, dated description of the work. |
| ‘Can UK users choose where data is stored?’ | The location and contractual conditions | Put the qualified answer beside its source. |
For example, a buyer looking for Google Ads support shouldn’t be sent to a general paid-media paragraph merely because it sounds similar. Equally, someone comparing Facebook Ads targeting needs platform-specific information rather than a broad definition of advertising.
This is where page planning matters. An AIO strategy for B2B service pages should make the offer, intended customer, evidence and next step easy to find. It can’t guarantee that an external AI service will retrieve or cite the page.
Choose an embedding model and maintain the index
Most marketing teams don’t need to build embedding models. They need to choose embedding models that perform well on real buyer questions, fit their technical requirements and remain manageable as content changes.
Compare models with your own questions
OpenAI’s text-embedding-3-small produces 1,536-dimensional text embeddings by default, while text-embedding-3-large produces 3,072-dimensional text embeddings. Embedding dimensionality describes vector length, not guaranteed answer quality. Test both against passages buyers should find, using real questions to assess semantic similarity.
A pretrained model is the sensible starting point for many teams. A bigger model won’t repair an unclear service page.
If specialist terminology repeatedly causes poor matches, test fine-tuning embeddings or contrastive learning on representative examples. Contrastive learning uses relevant and irrelevant example pairs to shape representations, so get technical support before adapting a model. For image-and-text material, test multimodal embeddings against relevant examples.
Dimensionality reduction can shrink vectors before storage in vector databases, but may affect retrieval fidelity. Test dimensionality reduction in your vector search workflow before adopting it.
Keep versions and permissions under control
Your index must use dimensions that match the model’s output. If you change models, don’t mix old and new vectors as though they share a latent space. Rebuild the affected index and rerun your retrieval tests.
Record source IDs, review dates and model versions. Apply document permissions before a passage reaches an answer, particularly when you index CRM notes alongside public pages. Retrieved text can also contain instructions that try to redirect the assistant, so treat source content as evidence rather than commands. Quality checks for AI-assisted SEO content remain necessary even when retrieval works as intended.
Measure answers against qualified demand
A system can retrieve a relevant-sounding passage through vector search and still miss the buyer’s real question. Test the complete route: question, retrieved source, answer, citation and the action someone can take afterwards.
Build a small buyer-question test set
Start with questions from sales calls, site search, support requests and paid-search terms. Include close variants and awkward cases: an old price, a named integration, a location restriction and a question your content cannot answer.
For each question, note the passage you expect and why. Check whether it appears amongst the retrieved results and whether the context window includes enough supporting passage. Confirm that the answer keeps its qualifications and each citation supports the sentence beside it. If dimensionality reduction is applied to text embeddings, check its effect on retrieval performance. Auditing B2B SEO content for lead quality helps you separate pages that attract attention from those that help a suitable buyer make progress.
Connect retrieval to business results
Track failed questions and stale sources, then look at what happens after an answer. Do suitable prospects view a service page, make an enquiry or continue searching because the answer was thin? Compare those patterns with CRM feedback, not just semantic similarity scores. Model or index changes can shift the latent space, so retest retrieval performance after updates.
Keep public AI search separate from your own RAG system. You can test the retrieval pipeline you control, but you cannot assume every public answer engine uses your index or the same embeddings. Use AI search visibility checks for buyer answer gaps to observe what external systems show, then verify whether those appearances bring useful enquiries.
Frequently asked questions
Do LLMs automatically search your website?
No. A standard model can generate an answer without opening your site. Search and RAG depend on the tools, sources and settings connected to it. Public AI services also differ in what they retrieve.
Are embeddings enough to match every buyer question?
No. Text embeddings use semantic similarity to match paraphrases, while exact names, dates and contractual details need keyword matching or filters. Multimodal embeddings can help with image and text content, but aren’t needed for text-only retrieval. Sources must still support the answer.
Should you use embeddings instead of SEO?
No. Clear SEO pages help buyers find and assess your offer, while embeddings can help a configured system find relevant passages within content. If you’re using PPC data to identify buyer questions, use it to improve the pages as well as the retrieval tests.
Make the match useful to the buyer
A buyer doesn’t care how closely text embeddings and vector search match, or what semantic similarity score they produce. They care whether the answer addresses their situation and holds up when they check the source. Clear, current content gives retrieval something worth finding.
Start with one repeated sales question, find the passage that should answer it and test what your system returns. If that exposes gaps across your pages and campaigns, bring them into a joined-up Digital marketing plan.